This page is a static rendering of the Jupyter notebook ocean_gpu_tutorial.ipynb. The raw notebook is available at https://github.com/cloudbank-project/cloudbank_showcase/blob/main/gpu_computing_oceanography/ocean_gpu_tutorial.ipynb.
🌊 Tutorial: Differentiable Ocean Dynamics with Reactant.jl
1. Introduction: Why Differentiable Modeling?
Traditionally, ocean models are "black boxes." We put parameters in, and we get a simulation out. But if we want to know "How does the wind in the Drake Passage affect the heat in the North Atlantic?", we usually have to run thousands of simulations.
Cue in the Adjoint Method (Automatic Differentiation):By using Reactant.jl and Enzyme.jl, we transform our simulation into a mathematical function that we can differentiate.
- Forward Pass: The ocean flows (Physics).
- Adjoint Pass: The sensitivities flow backward (Gradients).
2. The Physical Setup
Our simulation represents a Reentrant Channel.
- Architecture: ReactantState() — We are running on an NVIDIA Tesla T4 using XLA (Accelerated Linear Algebra).
- Grid: ImmersedBoundaryGrid — This allows us to simulate complex bottom topography (the "bumps" on the ocean floor) that trigger eddies.
- Forcing: We apply a zonal wind stress ($\tau_u$) and a surface heat flux ($Q$).
3. Understanding the Outputs
In this demo, we visualize three distinct layers of information:
A. The State (The "What")
- Temperature ($T$): Shows where the water is warm or cold.
- Sea Surface Height ($\eta$): Shows the "hills" and "valleys" of the ocean surface. High SSH usually indicates a warm core or a gyre.
- Velocity ($u, v$): Visualized with arrows to show the swirling eddies that transport heat and carbon.
B. The Sensitivity (The "Why")
This is the magic of the Adjoint. We aren't just looking at the ocean but also looking at its vulnerability.
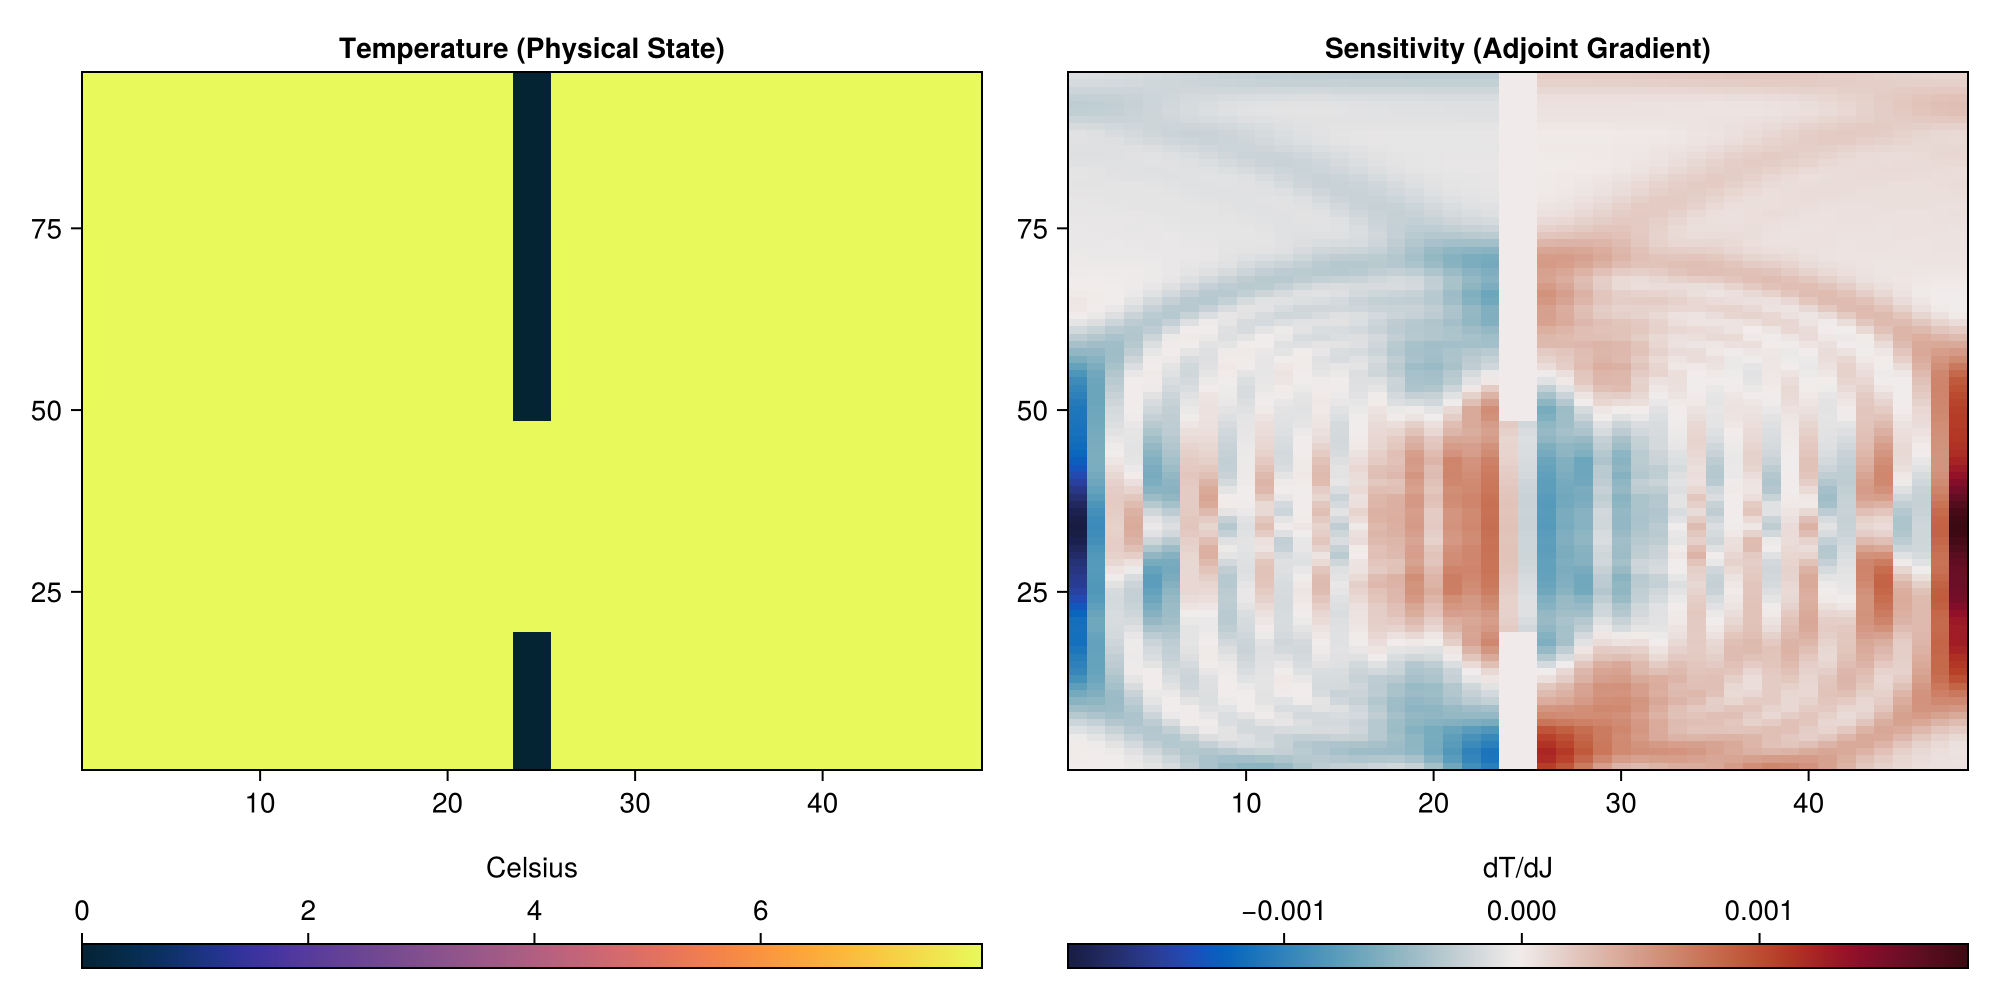
- $dT/dJ$: This heatmap shows exactly which initial temperature regions have the most influence on our final result.
- Wind Stress Sensitivity ($dJ/d\tau$): Shows where the model is most "sensitive" to wind. If a value is highly positive (Red), increasing the wind there will significantly increase our objective function.
Environment Setup
We recommend using juliaup, the official Julia version manager to handle the installation and path automatically in your VM
curl -fsSL [https://install.julialang.org](https://install.julialang.org) | sh
juliaup add 1.11
juliaup default 1.11
Oceananigans and Reactant require a working NVIDIA driver (i.e. the code will run faster on a GPU). Verify your driver version
nvidia-smi
Open the Julia REPL in your terminal by typing julia. Then, run these commands to set up the specific versions used in this tutorial. Packages are installed globally — do not call Pkg.activate(".") before this step:
using Pkg

Pkg.add([
    PackageSpec(name="Oceananigans", version="0.99.0"),
    PackageSpec(name="Reactant"),
    PackageSpec(name="Enzyme"),
    PackageSpec(name="CUDA"),
    PackageSpec(name="CairoMakie"),
    PackageSpec(name="ClimaOcean"),
    PackageSpec(name="SeawaterPolynomials"),
    PackageSpec(name="IJulia"),
    PackageSpec(name="JLD2"),
    PackageSpec(name="MPI"),
    PackageSpec(name="FileIO"),
])
Pkg.build("CUDA")
Precompilation takes 15–20 minutes on a T4 on first run.
To launch the notebook, you need to launch Jupyter and tunnel the port to your local machine
julia -e "using IJulia; notebook(dir=pwd(), detatched=true)"
For our simulation we use CUDA.jl . However, we need to ensure CUDA.jl and our local drivers are in sync.
using Pkg
Pkg.build("CUDA")
using CUDA
CUDA.versioninfo()
CUDA toolchain:
- runtime 13.2, artifact installation
- driver 535.288.1 for 13.2
- compiler 13.2, artifact installation

CUDA libraries:
- CUBLAS: 13.4.0
- CURAND: 10.4.2
- CUFFT: 12.2.0
- CUSOLVER: 12.2.0
- CUSPARSE: 12.7.10
- CUPTI: 2026.1.1 (API 13.2.1)
- NVML: 12.0.0+535.288.1

Julia packages:
- CUDA: 5.11.2
- GPUArrays: 11.5.3
- GPUCompiler: 1.9.1
- KernelAbstractions: 0.9.41
- CUDA_Driver_jll: 13.2.1+0
- CUDA_Compiler_jll: 0.4.3+0
- CUDA_Runtime_jll: 0.21.0+1

Toolchain:
- Julia: 1.11.9
- LLVM: 16.0.6

1 device:
  0: Tesla T4 (sm_75, 14.576 GiB / 15.000 GiB available)
# Packages are pre-installed; just load them
using Reactant, Enzyme, CUDA
Dependencies and Backend Setup
First, we load the necessary libraries. Note the inclusion of Reactant and Enzyme.
- Reactant.jl allows us to compile Oceananigans kernels for the GPU/XLA.
- Enzyme.jl is the engine that performs "Automatic Differentiation" (AD), allowing us to calculate sensitivities (gradients) through the physics.
using Pkg
using Printf
using Statistics
using Oceananigans
using Oceananigans.Units
using Oceananigans.OutputReaders: FieldTimeSeries
using Oceananigans.Grids: xnode, ynode, znode
using Oceananigans.TurbulenceClosures: CATKEVerticalDiffusivity, HorizontalFormulation

using SeawaterPolynomials

using ClimaOcean.Diagnostics: MixedLayerDepthField

using Reactant
using Oceananigans.Architectures: ReactantState
using Enzyme
[33m[1m┌ [22m[39m[33m[1mWarning: [22m[39mYou are using Julia v1.11 or later!"
[33m[1m│ [22m[39mOceananigans is currently tested on Julia v1.10."
[33m[1m│ [22m[39mIf you find issues with Julia v1.11 or later,"
[33m[1m│ [22m[39mplease report at https://github.com/CliMA/Oceananigans.jl/issues/new
[33m[1m└ [22m[39m[90m@ Oceananigans ~/.julia/packages/Oceananigans/G5zjl/src/Oceananigans.jl:125[39m
Model Parameters and Grid Geometry
We define a Reentrant Channel. We use a "stretched grid" in the vertical ($z$) direction, which provides higher resolution near the surface where the wind and heat fluxes act.
Oceananigans.defaults.FloatType = Float64

const Ntimesteps = 25        # Number of timesteps in zonal transport computed / AD'ed part
const Nspinup    = 25        # Number of timesteps that the model is spun up

graph_directory = "run_abernathy_model_ad_spinup" * string(Nspinup) * "_" * string(Ntimesteps) * "steps/"

#
# Model parameters to set first:
#

# number of grid points
const Nx = 48  # LowRes: 48
const Ny = 96 # LowRes: 96
const Nz = 32

const x_midpoint = Int(Nx / 2) + 1

# stretched grid
k_center = collect(1:Nz)
Δz_center = @. 10 * 1.104^(Nz - k_center)

const Lx = 1000kilometers # zonal domain length [m]
const Ly = 2000kilometers # meridional domain length [m]
const Lz = sum(Δz_center)

z_faces = vcat([-Lz], -Lz .+ cumsum(Δz_center))
z_faces[Nz+1] = 0

Δz = z_faces[2:end] - z_faces[1:end-1]

Δz = reshape(Δz, 1, :)

# Coriolis variables:
const f = -1e-4
const β = 1e-11

halo_size = 4 #3 for non-immersed grid

# Other model parameters:
const α = 2e-4     # [K⁻¹] thermal expansion coefficient
const g = 9.8061   # [m/s²] gravitational constant
const cᵖ = 3994.0   # [J/K]  heat capacity
const ρ = 999.8    # [kg/m³] reference density

parameters = (
    Ly = Ly,
    Lz = Lz,
    Qᵇ = 10 / (ρ * cᵖ) * α * g,            # buoyancy flux magnitude [m² s⁻³]
    Qᵀ = 10 / (ρ * cᵖ),                    # temperature flux magnitude
    y_shutoff = 5 / 6 * Ly,                # shutoff location for buoyancy flux [m]
    τ = 0.2 / ρ,                           # surface kinematic wind stress [m² s⁻²]
    μ = 1 / 30days,                      # bottom drag damping time-scale [s⁻¹]
    ΔB = 8 * α * g,                      # surface vertical buoyancy gradient [s⁻²]
    ΔT = 8,                              # surface vertical temperature gradient
    H = Lz,                              # domain depth [m]
    h = 1000.0,                          # exponential decay scale of stable stratification [m]
    y_sponge = 19 / 20 * Ly,               # southern boundary of sponge layer [m]
    λt = 7.0days                         # relaxation time scale [s]
)
(Ly = 2.0e6, Lz = 2184.0675121055447, Qᵇ = 4.911397903015757e-9, Qᵀ = 2.504256484747125e-6, y_shutoff = 1.6666666666666667e6, τ = 0.00020004000800160035, μ = 3.8580246913580245e-7, ΔB = 0.01568976, ΔT = 8, H = 2184.0675121055447, h = 1000.0, y_sponge = 1.9e6, λt = 604800.0)
Topography and Model Building
We define a Ridge (underwater mountain) using an Immersed Boundary. This ridge is crucial because it disrupts the flow and generates the "eddies" (oceanic weather) we want to study. Furthermore, we define a "Forward" simulation and an "Adjoint" calculation.
-
estimate_tracer_error: This function runs the model and returns a single number (Zonal Transport in Sverdrups). -
differentiate_tracer_error: This uses Enzyme to work backward from that single number to find the sensitivity of the entire ocean state to our inputs (Wind, Heat, etc.).
function ridge_function(x, y)
    zonal = (Lz+3000)exp(-(x - Lx/2)^2/(1e6kilometers))
    gap   = 1 - 0.5(tanh((y - (Ly/6))/1e5) - tanh((y - (Ly/2))/1e5))
    return zonal * gap - Lz
end

function wall_function(x, y)
    zonal = (x > 470kilometers) && (x < 530kilometers)
    gap   = (y < 400kilometers) || (y > 1000kilometers)
    return (Lz+1) * zonal * gap - Lz
end


function make_grid(architecture, Nx, Ny, Nz, z_faces)

    underlying_grid = RectilinearGrid(architecture,
        topology = (Periodic, Bounded, Bounded),
        size = (Nx, Ny, Nz),
        halo = (halo_size, halo_size, halo_size),
        x = (0, Lx),
        y = (0, Ly),
        z = z_faces)

    # Make into a ridge array:
    ridge = Field{Center, Center, Nothing}(underlying_grid)
    set!(ridge, wall_function)

    grid = ImmersedBoundaryGrid(underlying_grid, GridFittedBottom(ridge))
    return grid
end

#####
##### Model construction:
#####

function build_model(grid, Δt₀, parameters)

    temperature_flux_bc = FluxBoundaryCondition(Field{Center, Center, Nothing}(grid))

    u_stress_bc = FluxBoundaryCondition(Field{Face, Center, Nothing}(grid))
    v_stress_bc = FluxBoundaryCondition(Field{Center, Face, Nothing}(grid))

    @inline u_drag(i, j, grid, clock, model_fields, p) = @inbounds -p.μ * p.Lz * model_fields.u[i, j, 1]
    @inline v_drag(i, j, grid, clock, model_fields, p) = @inbounds -p.μ * p.Lz * model_fields.v[i, j, 1]

    u_drag_bc = FluxBoundaryCondition(u_drag, discrete_form = true, parameters = parameters)
    v_drag_bc = FluxBoundaryCondition(v_drag, discrete_form = true, parameters = parameters)

    T_bcs = FieldBoundaryConditions(top = temperature_flux_bc)

    u_bcs = FieldBoundaryConditions(top = u_stress_bc, bottom = u_drag_bc)
    v_bcs = FieldBoundaryConditions(top = v_stress_bc, bottom = v_drag_bc)

    #####
    ##### Coriolis
    #####
    coriolis = BetaPlane(f₀ = f, β = β)

    #####
    ##### Forcing and initial condition
    #####
    @inline initial_temperature(z, p) = p.ΔT * (exp(z / p.h) - exp(-p.Lz / p.h)) / (1 - exp(-p.Lz / p.h))
    @inline mask(y, p)                = max(0.0, y - p.y_sponge) / (Ly - p.y_sponge)

    @inline function temperature_relaxation(i, j, k, grid, clock, model_fields, p)
        timescale = p.λt
        y = ynode(j, grid, Center())
        z = znode(k, grid, Center())
        target_T = initial_temperature(z, p)
        T = @inbounds model_fields.T[i, j, k]

        return -1 / timescale * mask(y, p) * (T - target_T)
    end

    FT = Forcing(temperature_relaxation, discrete_form = true, parameters = parameters)

    # closure (moderately elevating scalar visc/diff)

    κh = 5e-5 # [m²/s] horizontal diffusivity
    νh = 500  # [m²/s] horizontal viscocity
    κz = 5e-5 # [m²/s] vertical diffusivity
    νz = 3e-3 # [m²/s] vertical viscocity

    κz_field = Field{Center, Center, Center}(grid)
    κz_array = zeros(Nx, Ny, Nz)

    κz_add = 5e-5  # m² / s at surface
    decay_scale = 5   # layers
    for k in 1:Nz
        taper = exp(- (k-1) / decay_scale)
        κz_array[:,:,k] .= κz + κz_add * taper
    end

    set!(κz_field, κz_array)

    horizontal_closure = HorizontalScalarDiffusivity(ν = νh, κ = κh)
    vertical_closure = VerticalScalarDiffusivity(ν = νz, κ = κz_field)

    biharmonic_closure = ScalarBiharmonicDiffusivity(HorizontalFormulation(), Oceananigans.defaults.FloatType;
                                                     ν = 1e11)

    @info "Building a model..."

    model = HydrostaticFreeSurfaceModel(
        grid = grid,
        free_surface = SplitExplicitFreeSurface(substeps=10),
        momentum_advection = WENO(order=3),
        tracer_advection = WENO(order=3),
        buoyancy = SeawaterBuoyancy(equation_of_state=LinearEquationOfState(Oceananigans.defaults.FloatType)),
        coriolis = coriolis,
        closure = (horizontal_closure, vertical_closure, biharmonic_closure),
        tracers = (:T, :S, :e),
        boundary_conditions = (T = T_bcs, u = u_bcs, v = v_bcs),
        forcing = (T = FT,)
    )

    model.clock.last_Δt = Δt₀

    return model
end

#####
##### Special initial and boundary conditions
#####

# Temperature flux:
function T_flux_init(grid, p)
    @inline temp_flux_function(x, y) = ifelse(y < p.y_shutoff, p.Qᵀ * cos(3π * y / p.Ly), 0.0)
    temp_flux = Field{Center, Center, Nothing}(grid)
    @allowscalar set!(temp_flux, temp_flux_function)
    return temp_flux
end

# wind stress:
function u_wind_stress_init(grid, p)
    @inline u_stress(x, y) = -p.τ * sin(π * y / p.Ly)
    wind_stress = Field{Face, Center, Nothing}(grid)
    @allowscalar set!(wind_stress, u_stress)
    return wind_stress
end

function v_wind_stress_init(grid, p)
    wind_stress = Field{Center, Face, Nothing}(grid)
    @allowscalar set!(wind_stress, 0)
    return wind_stress
end

# resting initial condition
function temperature_salinity_init(grid, parameters)
    # Adding some noise to temperature field:
    ε(σ) = σ * randn()
    Tᵢ_function(x, y, z) = parameters.ΔT * (exp(z / parameters.h) - exp(-Lz / parameters.h)) / (1 - exp(-Lz / parameters.h)) + ε(1e-8)
    Tᵢ = Field{Center, Center, Center}(grid)
    Sᵢ = Field{Center, Center, Center}(grid)
    @allowscalar set!(Tᵢ, Tᵢ_function)
    @allowscalar set!(Sᵢ, 35) # Initial Salinity
    return Tᵢ, Sᵢ
end

#####
##### Spin up (because step cound is hardcoded we need separate functions for each loop...)
#####

function spinup_loop!(model)
    Δt = model.clock.last_Δt
    @trace mincut = true track_numbers = false for i = 1:Nspinup
        time_step!(model, Δt)
    end
    return nothing
end

function spinup_reentrant_channel_model!(model, Tᵢ, Sᵢ, u_wind_stress, v_wind_stress, temp_flux)
    # setting IC's and BC's:
    set!(model.velocities.u.boundary_conditions.top.condition, u_wind_stress)
    set!(model.velocities.v.boundary_conditions.top.condition, v_wind_stress)
    set!(model.tracers.T, Tᵢ)
    set!(model.tracers.S, Sᵢ)
    set!(model.tracers.T.boundary_conditions.top.condition, temp_flux)

    # Initialize the model
    model.clock.iteration = 0
    model.clock.time = 0

    # Step it forward
    spinup_loop!(model)

    return nothing
end

#####
##### Forward simulation (not actually using the Simulation struct)
#####

function loop!(model)
    Δt = model.clock.last_Δt
    @trace mincut = true checkpointing = true track_numbers = false for i = 1:Ntimesteps
        time_step!(model, Δt)
    end
    return nothing
end

function run_reentrant_channel_model!(model, Tᵢ, Sᵢ, u_wind_stress, v_wind_stress, temp_flux)
    # setting IC's and BC's:
    set!(model.velocities.u.boundary_conditions.top.condition, u_wind_stress)
    set!(model.velocities.v.boundary_conditions.top.condition, v_wind_stress)
    set!(model.tracers.T, Tᵢ)
    set!(model.tracers.S, Sᵢ)
    set!(model.tracers.T.boundary_conditions.top.condition, temp_flux)

    # Initialize the model
    model.clock.iteration = 0
    model.clock.time = 0

    # Step it forward
    loop!(model)

    return nothing
end

function estimate_tracer_error(model, initial_temperature, initial_salinity, u_wind_stress, v_wind_stress, temp_flux, Δz, mld)
    run_reentrant_channel_model!(model, initial_temperature, initial_salinity, u_wind_stress, v_wind_stress, temp_flux)

    Nx, Ny, Nz = size(model.grid)

    # Compute the zonal transport:
    zonal_transport = (model.velocities.u[x_midpoint,1:Ny,1:Nz] .* model.grid.Δyᵃᶜᵃ) .* Δz

    return sum(zonal_transport) / 1e6 # Put it in Sverdrups
end

function differentiate_tracer_error(model, Tᵢ, Sᵢ, u_wind_stress, v_wind_stress, temp_flux, Δz, mld,
                                   dmodel, dTᵢ, dSᵢ, du_wind_stress, dv_wind_stress, dtemp_flux, dΔz, dmld)

    dedν = autodiff(set_strong_zero(Enzyme.ReverseWithPrimal),
                    estimate_tracer_error, Active,
                    Duplicated(model, dmodel),
                    Duplicated(Tᵢ, dTᵢ),
                    Duplicated(Sᵢ, dSᵢ),
                    Duplicated(u_wind_stress, du_wind_stress),
                    Duplicated(v_wind_stress, dv_wind_stress),
                    Duplicated(temp_flux, dtemp_flux),
                    Duplicated(Δz, dΔz),
                    Duplicated(mld, dmld))

    return dedν
end
differentiate_tracer_error (generic function with 1 method)
Model Initialization and Physical Fields
Now we initialize the physical state. We set the architecture to ReactantState() to ensure all calculations happen on the GPU/XLA device. We also initialize our boundary conditions (Wind and Heat Flux) and our initial conditions (Temperature and Salinity).
architecture = ReactantState()

# Timestep size:
Δt₀ = 2.5minutes

# Make the grid:
grid          = make_grid(architecture, Nx, Ny, Nz, z_faces)
model         = build_model(grid, Δt₀, parameters)
T_flux        = T_flux_init(model.grid, parameters)
u_wind_stress = u_wind_stress_init(model.grid, parameters)
v_wind_stress = v_wind_stress_init(model.grid, parameters)
Tᵢ, Sᵢ        = temperature_salinity_init(model.grid, parameters)
mld           = MixedLayerDepthField(model.buoyancy, model.grid, model.tracers)
Δz            = Reactant.ConcreteRArray(Δz)

@info "Built $model."
WARNING: All log messages before absl::InitializeLog() is called are written to STDERR
I0000 00:00:1776994623.326531 115936 service.cc:154] XLA service 0x419749c0 initialized for platform CUDA (this does not guarantee that XLA will be used). Devices:
I0000 00:00:1776994623.326587 115936 service.cc:170] StreamExecutor [0]: Tesla T4, Compute Capability 7.5 (Driver: 13.2.0[535.288.1]; Runtime: 12.9.0; Toolkit: 12.9.0; DNN: 9.14.0)
I0000 00:00:1776994623.327340 115936 se_gpu_pjrt_client.cc:1540] Using BFC allocator.
I0000 00:00:1776994623.327442 115936 gpu_helpers.cc:141] XLA backend allocating 11741872128 bytes on device 0 for BFCAllocator.
I0000 00:00:1776994623.327493 115936 gpu_helpers.cc:183] XLA backend will use up to 3913957376 bytes on device 0 for CollectiveBFCAllocator.
I0000 00:00:1776994623.342274 115936 cuda_dnn.cc:461] Loaded cuDNN version 91400
[36m[1m[ [22m[39m[36m[1mInfo: [22m[39mBuilding a model...
[36m[1m┌ [22m[39m[36m[1mInfo: [22m[39mBuilt HydrostaticFreeSurfaceModel{ReactantState, ImmersedBoundaryGrid}(time = 0 seconds, iteration = ConcretePJRTNumber(0))
[36m[1m│ [22m[39m├── grid: 48×96×32 ImmersedBoundaryGrid{Float64, Periodic, Bounded, Bounded} on ReactantState with 4×4×4 halo
[36m[1m│ [22m[39m├── timestepper: QuasiAdamsBashforth2TimeStepper
[36m[1m│ [22m[39m├── tracers: (T, S, e)
[36m[1m│ [22m[39m├── closure: Tuple with 3 closures:
[36m[1m│ [22m[39m│ ├── HorizontalScalarDiffusivity{ExplicitTimeDiscretization}(ν=500.0, κ=(T=5.0e-5, S=5.0e-5, e=5.0e-5))
[36m[1m│ [22m[39m│ ├── VerticalScalarDiffusivity{ExplicitTimeDiscretization}(ν=0.003, κ=(T=48×96×32 Field{Center, Center, Center} on ImmersedBoundaryGrid on ReactantState, S=48×96×32 Field{Center, Center, Center} on ImmersedBoundaryGrid on ReactantState, e=48×96×32 Field{Center, Center, Center} on ImmersedBoundaryGrid on ReactantState))
[36m[1m│ [22m[39m│ └── ScalarBiharmonicDiffusivity{HorizontalFormulation}(ν=1.0e11, κ=(T=0.0, S=0.0, e=0.0))
[36m[1m│ [22m[39m├── buoyancy: SeawaterBuoyancy with g=9.80665 and LinearEquationOfState(thermal_expansion=0.000167, haline_contraction=0.00078) with ĝ = NegativeZDirection()
[36m[1m│ [22m[39m├── free surface: SplitExplicitFreeSurface with gravitational acceleration 9.80665 m s⁻²
[36m[1m│ [22m[39m│ └── substepping: FixedSubstepNumber(7)
[36m[1m│ [22m[39m├── advection scheme:
[36m[1m│ [22m[39m│ ├── momentum: WENO{2, Float64, Float32}(order=3)
[36m[1m│ [22m[39m│ ├── T: WENO{2, Float64, Float32}(order=3)
[36m[1m│ [22m[39m│ ├── S: WENO{2, Float64, Float32}(order=3)
[36m[1m│ [22m[39m│ └── e: WENO{2, Float64, Float32}(order=3)
[36m[1m│ [22m[39m├── vertical_coordinate: ZCoordinate
[36m[1m└ [22m[39m└── coriolis: BetaPlane{Float64}.
Compilation
To compute gradients, Enzyme requires "Shadow" variables. For every physical field (like model or Tᵢ), we create a matching zero field (dmodel or dTᵢ). These shadows will store the sensitivity values (the gradients) during the reverse pass.
We then use @compile to fuse these operations into high-performance XLA kernels.
dmodel         = Enzyme.make_zero(model)
dTᵢ            = Field{Center, Center, Center}(model.grid)
dSᵢ            = Field{Center, Center, Center}(model.grid)
du_wind_stress = Field{Face, Center, Nothing}(model.grid)
dv_wind_stress = Field{Center, Face, Nothing}(model.grid)
dT_flux        = Field{Center, Center, Nothing}(model.grid)
dmld           = MixedLayerDepthField(dmodel.buoyancy, dmodel.grid, dmodel.tracers)
dΔz            = Enzyme.make_zero(Δz)

@info "Compiling..."
@info "Running Spinup..."
rspinup_reentrant_channel_model! = @compile raise_first=true raise=true sync=true spinup_reentrant_channel_model!(model, Tᵢ, Sᵢ, u_wind_stress, v_wind_stress, T_flux)

@info "Computing Gradients..."
rdifferentiate_tracer_error = @compile raise_first=true raise=true sync=true  differentiate_tracer_error(model, Tᵢ, Sᵢ, u_wind_stress, v_wind_stress, T_flux, Δz, mld,
                                   dmodel, dTᵢ, dSᵢ, du_wind_stress, dv_wind_stress, dT_flux, dΔz, dmld)
@info "Compilation complete."
[36m[1m[ [22m[39m[36m[1mInfo: [22m[39mCompiling...
[36m[1m[ [22m[39m[36m[1mInfo: [22m[39mRunning Spinup...
I0000 00:00:1776996365.546605 115936 subprocess_compilation.cc:348] ptxas warning : Registers are spilled to local memory in function 'loop_subtract_fusion', 1384 bytes spill stores, 1380 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 12 bytes spill stores, 16 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_select_subtract_fusion', 1904 bytes spill stores, 1748 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 32 bytes spill stores, 36 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_compare_multiply_subtract_fusion', 5716 bytes spill stores, 6180 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
[36m[1m[ [22m[39m[36m[1mInfo: [22m[39mComputing Gradients...
I0000 00:00:1776996582.872225 116072 subprocess_compilation.cc:348] ptxas warning : Registers are spilled to local memory in function 'input_add_divide_multiply_reduce_select_subtract_fusion', 2532 bytes spill stores, 2656 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 8 bytes spill stores, 12 bytes spill loads
E0000 00:00:1776996709.163311 116077 slow_operation_alarm.cc:73]
********************************
[Compiling module reactant_differe... for GPU] Very slow compile? If you want to file a bug, run with envvar XLA_FLAGS=--xla_dump_to=/tmp/foo and attach the results.
********************************
I0000 00:00:1776996733.815068 115936 subprocess_compilation.cc:348] ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 4 bytes spill stores, 4 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_43', 224 bytes spill stores, 208 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_select_subtract_fusion', 1912 bytes spill stores, 1920 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_39', 152 bytes spill stores, 152 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_44', 1088 bytes spill stores, 1080 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_subtract_fusion', 764 bytes spill stores, 672 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_divide_multiply_select_subtract_fusion_1', 592 bytes spill stores, 592 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_46', 64 bytes spill stores, 64 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_divide_multiply_select_subtract_fusion_3', 528 bytes spill stores, 528 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_42', 460 bytes spill stores, 444 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_45', 120 bytes spill stores, 120 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_40', 128 bytes spill stores, 128 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'input_add_divide_multiply_reduce_select_subtract_fusion', 2580 bytes spill stores, 2704 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 8 bytes spill stores, 12 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_divide_multiply_select_subtract_fusion_2', 488 bytes spill stores, 488 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_divide_multiply_select_subtract_fusion_4', 508 bytes spill stores, 508 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_50', 364 bytes spill stores, 348 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_divide_multiply_select_fusion_1', 1204 bytes spill stores, 1196 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 32 bytes spill stores, 36 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_32', 1564 bytes spill stores, 1576 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 4 bytes spill stores, 4 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_select_fusion_2', 112 bytes spill stores, 112 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_31', 1576 bytes spill stores, 1584 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 4 bytes spill stores, 4 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_compare_multiply_select_fusion_1', 1336 bytes spill stores, 1328 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 16 bytes spill stores, 20 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_select_fusion_1', 80 bytes spill stores, 56 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_select_fusion_3', 1292 bytes spill stores, 1300 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_compare_multiply_select_fusion', 1308 bytes spill stores, 1316 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_broadcast_select_subtract_fusion', 416 bytes spill stores, 360 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_49', 1232 bytes spill stores, 1176 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 16 bytes spill stores, 20 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_fusion_37', 40 bytes spill stores, 40 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_compare_multiply_fusion', 428 bytes spill stores, 428 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_compare_divide_multiply_subtract_fusion', 1740 bytes spill stores, 1732 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 12 bytes spill stores, 16 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_broadcast_compare_divide_multiply_select_fusion', 792 bytes spill stores, 784 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 20 bytes spill stores, 24 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_compare_multiply_select_subtract_fusion', 1164 bytes spill stores, 1156 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 4 bytes spill stores, 4 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_compare_concatenate_divide_multiply_select_subtract_fusion', 1088 bytes spill stores, 1056 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 20 bytes spill stores, 24 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_compare_multiply_select_subtract_fusion_1', 1828 bytes spill stores, 1836 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_multiply_select_subtract_fusion', 784 bytes spill stores, 760 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_subtract_fusion_1', 48 bytes spill stores, 48 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_concatenate_divide_multiply_select_subtract_fusion', 1780 bytes spill stores, 1788 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_concatenate_divide_multiply_select_subtract_fusion_1', 1828 bytes spill stores, 1796 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 12 bytes spill stores, 16 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_broadcast_compare_divide_multiply_subtract_fusion', 1708 bytes spill stores, 1716 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_add_compare_concatenate_divide_multiply_select_subtract_fusion_1', 1068 bytes spill stores, 1072 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_subtract_fusion_2', 1368 bytes spill stores, 1356 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 12 bytes spill stores, 16 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_select_subtract_fusion_1', 1904 bytes spill stores, 1748 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 12 bytes spill stores, 12 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 40 bytes spill stores, 44 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_compare_multiply_subtract_fusion_1', 5892 bytes spill stores, 5820 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 20 bytes spill stores, 20 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_subtract_fusion', 1384 bytes spill stores, 1380 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 12 bytes spill stores, 16 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_select_subtract_fusion', 1904 bytes spill stores, 1748 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_div_rn_f64_full', 32 bytes spill stores, 36 bytes spill loads
ptxas warning : Registers are spilled to local memory in function 'loop_compare_multiply_subtract_fusion', 5716 bytes spill stores, 6180 bytes spill loads
ptxas warning : Registers are spilled to local memory in function '__cuda_sm20_dblrcp_rn_slowpath_v3', 8 bytes spill stores, 8 bytes spill loads
E0000 00:00:1776996736.349411 115936 slow_operation_alarm.cc:140] The operation took 2m27.186269977s
********************************
[Compiling module reactant_differe... for GPU] Very slow compile? If you want to file a bug, run with envvar XLA_FLAGS=--xla_dump_to=/tmp/foo and attach the results.
********************************
[36m[1m[ [22m[39m[36m[1mInfo: [22m[39mCompilation complete.
Data Handling and Visualization
Our modle ha scompiled and run! Ideally, the model compilation should not take more than a few minutes. If it is, you are mostly running it on a CPU rather than a GPU. Now, we ensure the environment has the necessary tools to save our results (JLD2) and visualize the gradients (CairoMakie)
import Pkg; Pkg.add("FileIO")
import Pkg; Pkg.add("JLD2")
import Pkg; Pkg.add("CairoMakie")
[32m[1m Updating[22m[39m registry at `~/.julia/registries/General.toml`
[32m[1m Resolving[22m[39m package versions...
[32m[1m No Changes[22m[39m to `~/.julia/environments/v1.11/Project.toml`
[32m[1m No Changes[22m[39m to `~/.julia/environments/v1.11/Manifest.toml`
[32m[1m Resolving[22m[39m package versions...
[32m[1m No Changes[22m[39m to `~/.julia/environments/v1.11/Project.toml`
[32m[1m No Changes[22m[39m to `~/.julia/environments/v1.11/Manifest.toml`
[32m[1m Resolving[22m[39m package versions...
[32m[1m No Changes[22m[39m to `~/.julia/environments/v1.11/Project.toml`
[32m[1m No Changes[22m[39m to `~/.julia/environments/v1.11/Manifest.toml`
Before we compute gradients, we "Spinup" the model to allow the physical fields to adjust to the topography and forcing. We then save this state to a .jld2 file. Note the use of convert(Array, interior(...)) to move data from the GPU/XLA memory back to the CPU for permanent storage.
Now we execute the main simulation. Instead of just a forward run, we use rdifferentiate_tracer_error to perform the backward pass via Enzyme. We wrap this in Reactant.Profiler.@profile to inspect the XLA kernel performance. You can remove Reactant.Profiler.@profile as well if you want to simply run the calculation.
using FileIO, JLD2

filename = graph_directory * "data_init.jld2"

if !isdir(graph_directory) Base.Filesystem.mkdir(graph_directory) end

if isa(model.grid, ImmersedBoundaryGrid)
    bottom_height = model.grid.immersed_boundary.bottom_height
else
    bottom_height = Field{Center, Center, Nothing}(model.grid)
    set!(bottom_height, -Lz)
end

@info "Spinup the model for $Nspinup timesteps, save the T and S from this state:"
tic = time()
rspinup_reentrant_channel_model!(model, Tᵢ, Sᵢ, u_wind_stress, v_wind_stress, T_flux)
@allowscalar set!(Tᵢ, model.tracers.T)
@allowscalar set!(Sᵢ, model.tracers.S)
spinup_toc = time() - tic
@show spinup_toc

jldsave(filename; Nx, Ny, Nz,
                  bottom_height=convert(Array, interior(bottom_height)),
                  T_init=convert(Array, interior(model.tracers.T)),
                  S_init=convert(Array, interior(model.tracers.S)),
                  ssh=convert(Array, interior(model.free_surface.η)),
                  e_init=convert(Array, interior(model.tracers.e)),
                  u_wind_stress=convert(Array, interior(u_wind_stress)),
                  v_wind_stress=convert(Array, interior(v_wind_stress)),
                  dkappaT_init=convert(Array, interior(dmodel.closure[2].κ[1])),
                  dkappaS_init=convert(Array, interior(dmodel.closure[2].κ[2])),
                  T_flux=convert(Array, interior(T_flux)))


@info "Running the simulation for $Ntimesteps timesteps ... (if you want to run the forward code only, just run 'restimate_tracer_error')"
tic = time()
#Reactant.Profiler.@profile output = restimate_tracer_error(model, Tᵢ, Sᵢ, u_wind_stress, v_wind_stress, T_flux, Δz, mld)
Reactant.Profiler.@profile rdifferentiate_tracer_error(model, Tᵢ, Sᵢ, u_wind_stress, v_wind_stress, T_flux, Δz, mld, dmodel, dTᵢ, dSᵢ, du_wind_stress, dv_wind_stress, dT_flux, dΔz, dmld)
run_toc = time() - tic

@info "Run toc gives you the combined time of the warmup run and the counted run from @profile, so it should be somewhat over 2x the time of profile"
@show run_toc
#@show output

#@show dedν

filename = graph_directory * "data_final.jld2"

jldsave(filename; Nx, Ny, Nz,
                  T_final=convert(Array, interior(model.tracers.T)),
                  S_final=convert(Array, interior(model.tracers.S)),
                  e_final=convert(Array, interior(model.tracers.e)),
                  ssh=convert(Array, interior(model.free_surface.η)),
                  u=convert(Array, interior(model.velocities.u)),
                  v=convert(Array, interior(model.velocities.v)),
                  w=convert(Array, interior(model.velocities.w)),
                  mld=convert(Array, interior(mld)),
                  #zonal_transport=convert(Float64, output),
                  #zonal_transport=convert(Float64, dedν[2]),
                  du_wind_stress=convert(Array, interior(du_wind_stress)),
                  dv_wind_stress=convert(Array, interior(dv_wind_stress)),
                  dT=convert(Array, interior(dTᵢ)),
                  dS=convert(Array, interior(dSᵢ)),
                  dkappaT_final=convert(Array, interior(dmodel.closure[2].κ[1])),
                  dkappaS_final=convert(Array, interior(dmodel.closure[2].κ[2])),
                  dT_flux=convert(Array, interior(dT_flux)))
spinup_toc = 21.20083498954773
[36m[1m[ [22m[39m[36m[1mInfo: [22m[39mSpinup the model for 25 timesteps, save the T and S from this state:
[36m[1m[ [22m[39m[36m[1mInfo: [22m[39mRunning the simulation for 25 timesteps ... (if you want to run the forward code only, just run 'restimate_tracer_error')
I0000 00:00:1776996921.261252 115936 profiler_session.cc:119] Profiler session initializing.
I0000 00:00:1776996921.261329 115936 profiler_session.cc:134] Profiler session started.
I0000 00:00:1776996921.261395 115936 cupti_tracer.cc:1112] Profiler found 1 GPUs
I0000 00:00:1776996921.261438 115936 cuda_version_variants.cc:36] CUDA runtime version: 12090
I0000 00:00:1776996921.261444 115936 cuda_version_variants.cc:52] CUDA driver version: 13020
I0000 00:00:1776996923.833413 115936 profiler_session.cc:82] Profiler session collecting data.
I0000 00:00:1776996924.145623 115936 cupti_tracer.cc:1522] CUPTI activity buffer flushed
I0000 00:00:1776996924.618776 115936 cupti_collector.cc:900] GpuTracer has collected 97366 callback api events and 101440 activity events.
I0000 00:00:1776996924.629267 115936 cupti_collector.cc:903] GpuTracer max callback_events: 2097152, max activity events: 2097152
I0000 00:00:1776996925.478234 115936 save_profile.cc:150] Collecting XSpace to repository: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25/julia-ocean-gpu.xplane.pb
I0000 00:00:1776996926.893419 115936 save_profile.cc:123] Creating directory: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996927.805534 115936 save_profile.cc:129] Dumped gzipped tool data for trace.json.gz to /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25/julia-ocean-gpu.trace.json.gz
I0000 00:00:1776996928.241135 115936 profiler_session.cc:152] Profiler session tear down.
I0000 00:00:1776996928.284050 115936 stub_factory.cc:163] Created gRPC channel for address: 0.0.0.0:45187
I0000 00:00:1776996928.286461 115936 grpc_server.cc:94] Server listening on 0.0.0.0:45187 with max_concurrent_requests 1
I0000 00:00:1776996928.304088 115936 xplane_to_tools_data_with_profile_processor.cc:142] serving tool: memory_profile with options: {} using ProfileProcessor session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996928.304190 115936 xplane_to_tools_data_with_profile_processor.cc:165] Using local processing for tool: memory_profile
I0000 00:00:1776996928.304215 115936 memory_profile_processor.cc:47] Processing memory profile for host: julia-ocean-gpu
I0000 00:00:1776996928.950094 115936 xplane_to_tools_data_with_profile_processor.cc:170] Total time for tool memory_profile: 648.121714ms session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996928.995893 115936 xplane_to_tools_data_with_profile_processor.cc:142] serving tool: op_profile with options: {} using ProfileProcessor session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996928.995951 115936 xplane_to_tools_data_with_profile_processor.cc:165] Using local processing for tool: op_profile
I0000 00:00:1776996928.995975 115936 multi_xplanes_to_op_stats.cc:118] ConvertMultiXSpaceToCombinedOpStatsWithCache: Started
I0000 00:00:1776996928.996196 115936 multi_xplanes_to_op_stats.cc:134] ConvertMultiXSpaceToCombinedOpStatsWithCache: Cache miss, calling ConvertMultiXSpacesToCombinedOpStats
I0000 00:00:1776996928.996204 115936 multi_xplanes_to_op_stats.cc:45] ConvertMultiXSpacesToCombinedOpStats: Started. Number of XSpaces: 1
I0000 00:00:1776996928.996214 115936 multi_xplanes_to_op_stats.cc:55] ConvertMultiXSpacesToCombinedOpStats: Starting to process XSpace 0/1
I0000 00:00:1776996929.532773 115936 derived_timeline.cc:693] GenerateDerivedTimeLines: creating derived_timeline_trace_events XprofThreadPoolExecutor
I0000 00:00:1776996929.532844 115936 xprof_thread_pool_executor.cc:22] Creating derived_timeline_trace_events XprofThreadPoolExecutor with 1 threads.
I0000 00:00:1776996929.533077 115936 derived_timeline.cc:705] GenerateDerivedTimeLines: waiting for derived_timeline_trace_events threads to join
I0000 00:00:1776996929.602571 115936 derived_timeline.cc:709] GenerateDerivedTimeLines: derived_timeline_trace_events threads joined successfully
W0000 00:00:1776996942.268261 115936 derived_timeline.cc:590] Found derived XLine with clashing display ID: 1. This will cause rendering issues in Trace Viewer.
I0000 00:00:1776996942.304646 115936 derived_timeline.cc:758] GenerateDerivedTimeLines: creating ProcessTensorCorePlanes XprofThreadPoolExecutor
I0000 00:00:1776996942.304710 115936 xprof_thread_pool_executor.cc:22] Creating ProcessTensorCorePlanes XprofThreadPoolExecutor with 1 threads.
I0000 00:00:1776996942.304849 115936 derived_timeline.cc:769] GenerateDerivedTimeLines: waiting for ProcessTensorCorePlanes threads to join
I0000 00:00:1776996942.305208 115936 derived_timeline.cc:772] GenerateDerivedTimeLines: ProcessTensorCorePlanes threads joined successfully
I0000 00:00:1776996955.186853 115936 xplane_to_op_stats.cc:405] ConvertXSpaceToOpStats: creating op_stats_threads XprofThreadPoolExecutor
I0000 00:00:1776996955.189435 115936 xprof_thread_pool_executor.cc:22] Creating op_stats_threads XprofThreadPoolExecutor with 4 threads.
I0000 00:00:1776996955.200648 115936 xplane_to_op_stats.cc:461] ConvertXSpaceToOpStats: Scheduled 1 OpMetricsDb generation tasks.
W0000 00:00:1776996955.351855 115936 xplane_to_op_stats.cc:559] No CoreDetails found for TPU device plane: /device:GPU:0
I0000 00:00:1776996955.353792 115936 xplane_to_op_stats.cc:417] ConvertXSpaceToOpStats: Combining 1 op_metrics_dbs.
I0000 00:00:1776996955.365414 115936 xplane_to_op_stats.cc:422] ConvertXSpaceToOpStats: Finished combining op_metrics_dbs.
I0000 00:00:1776996955.763425 115936 xplane_to_op_stats.cc:687] ConvertXSpaceToOpStats: Final OpStats size: 1725622 bytes (1.64568 MiB).
I0000 00:00:1776996956.188072 115936 multi_xplanes_to_op_stats.cc:67] ConvertMultiXSpacesToCombinedOpStats: Finished processing XSpace 0.
I0000 00:00:1776996956.200497 115936 multi_xplanes_to_op_stats.cc:72] ConvertMultiXSpacesToCombinedOpStats: Finished extracting all 1 OpStats. Time: 27.207702589s
I0000 00:00:1776996956.203933 115936 multi_xplanes_to_op_stats.cc:85] ConvertMultiXSpacesToCombinedOpStats: Starting ComputeStepIntersectionToMergeOpStats.
I0000 00:00:1776996956.205303 115936 multi_xplanes_to_op_stats.cc:94] ConvertMultiXSpacesToCombinedOpStats: Finished ComputeStepIntersectionToMergeOpStats in 6.185us
I0000 00:00:1776996956.205323 115936 multi_xplanes_to_op_stats.cc:99] ConvertMultiXSpacesToCombinedOpStats: Starting CombineAllOpStats.
I0000 00:00:1776996956.213486 115936 multi_xplanes_to_op_stats.cc:106] ConvertMultiXSpacesToCombinedOpStats: Finished CombineAllOpStats in 8.174892ms
I0000 00:00:1776996956.213521 115936 multi_xplanes_to_op_stats.cc:109] ConvertMultiXSpacesToCombinedOpStats: Overall Finished in 27.217328556s
I0000 00:00:1776996956.221299 115936 multi_xplanes_to_op_stats.cc:138] ConvertMultiXSpaceToCombinedOpStatsWithCache: Starting to write cache file.
I0000 00:00:1776996956.229310 115936 multi_xplanes_to_op_stats.cc:145] ConvertMultiXSpaceToCombinedOpStatsWithCache: Finished writing cache file.
I0000 00:00:1776996956.229344 115936 multi_xplanes_to_op_stats.cc:149] ConvertMultiXSpaceToCombinedOpStatsWithCache: Overall Finished in 27.233391341s
I0000 00:00:1776996956.469304 115936 xplane_to_tools_data_with_profile_processor.cc:170] Total time for tool op_profile: 27.475162372s session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996956.621894 115936 xplane_to_tools_data_with_profile_processor.cc:142] serving tool: overview_page with options: {} using ProfileProcessor session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996956.621944 115936 xplane_to_tools_data_with_profile_processor.cc:165] Using local processing for tool: overview_page
I0000 00:00:1776996956.621964 115936 overview_page_processor.cc:84] OverviewPageProcessor::ProcessSession: Started
I0000 00:00:1776996956.621970 115936 overview_page_processor.cc:86] OverviewPageProcessor::ProcessSession: Starting ConvertMultiXSpaceToCombinedOpStatsWithCache
I0000 00:00:1776996956.621975 115936 multi_xplanes_to_op_stats.cc:118] ConvertMultiXSpaceToCombinedOpStatsWithCache: Started
I0000 00:00:1776996956.622055 115936 multi_xplanes_to_op_stats.cc:126] ConvertMultiXSpaceToCombinedOpStatsWithCache: Cache hit, reading binary proto
I0000 00:00:1776996956.630061 115936 multi_xplanes_to_op_stats.cc:131] ConvertMultiXSpaceToCombinedOpStatsWithCache: Finished reading cache file.
I0000 00:00:1776996956.630112 115936 multi_xplanes_to_op_stats.cc:149] ConvertMultiXSpaceToCombinedOpStatsWithCache: Overall Finished in 8.155248ms
I0000 00:00:1776996956.630136 115936 overview_page_processor.cc:90] OverviewPageProcessor::ProcessSession: Starting ConvertOpStatsToOverviewPage
I0000 00:00:1776996956.630159 115936 op_stats_to_overview_page.cc:388] ConvertOpStatsToOverviewPage: Starting ComputeRunEnvironment
I0000 00:00:1776996956.630173 115936 op_stats_to_overview_page.cc:393] ConvertOpStatsToOverviewPage: Starting ComputeAnalysisResult
I0000 00:00:1776996956.638544 115936 op_stats_to_overview_page.cc:396] ConvertOpStatsToOverviewPage: Starting ConvertOpStatsToInputPipelineAnalysis
I0000 00:00:1776996956.639081 115936 op_stats_to_overview_page.cc:401] ConvertOpStatsToOverviewPage: Starting ComputeBottleneckAnalysis
I0000 00:00:1776996956.639096 115936 op_stats_to_overview_page.cc:407] ConvertOpStatsToOverviewPage: Starting ComputeGenericRecommendation
I0000 00:00:1776996956.639319 115936 op_stats_to_overview_page.cc:412] ConvertOpStatsToOverviewPage: Starting SetCommonRecommendation
I0000 00:00:1776996956.639335 115936 op_stats_to_overview_page.cc:425] ConvertOpStatsToOverviewPage: Starting PopulateOverviewDiagnostics
I0000 00:00:1776996956.639340 115936 op_stats_to_overview_page.cc:429] ConvertOpStatsToOverviewPage: Starting setting utilizations
I0000 00:00:1776996956.639344 115936 op_stats_to_overview_page.cc:435] ConvertOpStatsToOverviewPage: Overall Finished in 9.187427ms
I0000 00:00:1776996956.639351 115936 overview_page_processor.cc:94] OverviewPageProcessor::ProcessSession: Not a training run, Starting to convert inference stats.
I0000 00:00:1776996956.639382 115936 xprof_thread_pool_executor.cc:22] Creating ConvertMultiXSpaceToInferenceStats XprofThreadPoolExecutor with 1 threads.
I0000 00:00:1776996957.365630 115936 overview_page_processor.cc:99] OverviewPageProcessor::ProcessSession: Starting to compute InferenceLatency
I0000 00:00:1776996957.365693 115936 overview_page_processor.cc:104] OverviewPageProcessor::ProcessSession: Starting to serialize OverviewPage toJson
I0000 00:00:1776996957.366195 115936 overview_page_processor.cc:107] OverviewPageProcessor::ProcessSession: Starting to set Output
I0000 00:00:1776996957.366223 115936 overview_page_processor.cc:109] OverviewPageProcessor::ProcessSession: Overall Finished in 744.261388ms
I0000 00:00:1776996957.375184 115936 xplane_to_tools_data_with_profile_processor.cc:170] Total time for tool overview_page: 754.085106ms session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996957.659175 115936 xplane_to_tools_data_with_profile_processor.cc:142] serving tool: kernel_stats with options: {} using ProfileProcessor session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996957.659239 115936 xplane_to_tools_data_with_profile_processor.cc:165] Using local processing for tool: kernel_stats
I0000 00:00:1776996957.659256 115936 multi_xplanes_to_op_stats.cc:118] ConvertMultiXSpaceToCombinedOpStatsWithCache: Started
I0000 00:00:1776996957.659335 115936 multi_xplanes_to_op_stats.cc:126] ConvertMultiXSpaceToCombinedOpStatsWithCache: Cache hit, reading binary proto
I0000 00:00:1776996957.666750 115936 multi_xplanes_to_op_stats.cc:131] ConvertMultiXSpaceToCombinedOpStatsWithCache: Finished reading cache file.
I0000 00:00:1776996957.666777 115936 multi_xplanes_to_op_stats.cc:149] ConvertMultiXSpaceToCombinedOpStatsWithCache: Overall Finished in 7.532068ms
I0000 00:00:1776996957.688291 115936 xplane_to_tools_data_with_profile_processor.cc:170] Total time for tool kernel_stats: 29.702128ms session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996958.000771 115936 xplane_to_tools_data_with_profile_processor.cc:142] serving tool: framework_op_stats with options: {} using ProfileProcessor session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
I0000 00:00:1776996958.000829 115936 xplane_to_tools_data_with_profile_processor.cc:165] Using local processing for tool: framework_op_stats
I0000 00:00:1776996958.000852 115936 multi_xplanes_to_op_stats.cc:118] ConvertMultiXSpaceToCombinedOpStatsWithCache: Started
I0000 00:00:1776996958.000932 115936 multi_xplanes_to_op_stats.cc:126] ConvertMultiXSpaceToCombinedOpStatsWithCache: Cache hit, reading binary proto
I0000 00:00:1776996958.008582 115936 multi_xplanes_to_op_stats.cc:131] ConvertMultiXSpaceToCombinedOpStatsWithCache: Finished reading cache file.
I0000 00:00:1776996958.008628 115936 multi_xplanes_to_op_stats.cc:149] ConvertMultiXSpaceToCombinedOpStatsWithCache: Overall Finished in 7.800961ms
I0000 00:00:1776996958.069478 115936 xplane_to_tools_data_with_profile_processor.cc:170] Total time for tool framework_op_stats: 70.494759ms session_id: /home/zonca/.julia/scratchspaces/3c362404-f566-11ee-1572-e11a4b42c853/reactant_profiling/jl_VLKvpb/plugins/profile/2026_04_24_02_15_25
╔================================================================================╗
║ KERNEL STATISTICS ║
╚================================================================================╝
┌───────────────────────────────────────────────────────┬─────────────┬─────────
│[1m Kernel Name [0m│[1m Occurrences [0m│[1m Total [0m ⋯
├───────────────────────────────────────────────────────┼─────────────┼─────────
│ loop_compare_multiply_subtract_fusion │ 25 │[31;1m 0.0[0m ⋯
│ loop_compare_multiply_subtract_fusion_1 │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_fusion_30 │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_fusion_34 │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_fusion_35 │ 25 │[31;1m 0.0[0m ⋯
│ input_concatenate_fusion_99 │ 50 │[31;1m 0.0[0m ⋯
│ loop_add_divide_multiply_select_fusion_1 │ 50 │[31;1m 0.0[0m ⋯
│ loop_add_select_fusion_3 │ 50 │[31;1m 0.0[0m ⋯
│ loop_add_fusion_36 │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_fusion_33 │ 25 │[31;1m 0.0[0m ⋯
│ input_add_divide_multiply_reduce_select_subtract_f... │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_concatenate_divide_multiply_select_subtra... │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_concatenate_divide_multiply_select_subtra... │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_compare_multiply_select_subtract_fusion_1 │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_compare_divide_multiply_subtract_fusion │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_broadcast_compare_divide_multiply_subtrac... │ 25 │[31;1m 0.0[0m ⋯
│ loop_subtract_fusion_4 │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_select_subtract_fusion │ 25 │[31;1m 0.0[0m ⋯
│ loop_add_divide_multiply_select_subtract_fusion_2 │ 50 │[31;1m 0.0[0m ⋯
│ loop_add_subtract_fusion │ 25 │[31;1m 0.0[0m ⋯
│ input_concatenate_fusion_103 │ 25 │[31;1m 0.0[0m ⋯
│ loop_select_subtract_fusion │ 25 │[31;1m 0.0[0m ⋯
│ ⋮ │ ⋮ │ ⋱
└───────────────────────────────────────────────────────┴─────────────┴─────────
[36m 9 columns and 468 rows omitted[0m
╔================================================================================╗
║ FRAMEWORK OP STATISTICS ║
╚================================================================================╝
┌───────────────────────────────────────────────────────┬─────────┬─────────────
│[1m Operation [0m│[1m Type [0m│[1m Host/Devic[0m ⋯
├───────────────────────────────────────────────────────┼─────────┼─────────────
│ loop_compare_multiply_subtract_fusion │ Unknown │ Devic ⋯
│ loop_compare_multiply_subtract_fusion.1 │ Unknown │ Devic ⋯
│ loop_add_fusion.30 │ Unknown │ Devic ⋯
│ loop_add_fusion.34 │ Unknown │ Devic ⋯
│ loop_add_fusion.35 │ Unknown │ Devic ⋯
│ loop_add_fusion.36 │ Unknown │ Devic ⋯
│ loop_add_fusion.33 │ Unknown │ Devic ⋯
│ input_add_divide_multiply_reduce_select_subtract_f... │ Unknown │ Devic ⋯
│ loop_add_concatenate_divide_multiply_select_subtra... │ Unknown │ Devic ⋯
│ loop_add_concatenate_divide_multiply_select_subtra... │ Unknown │ Devic ⋯
│ loop_add_compare_multiply_select_subtract_fusion.1 │ Unknown │ Devic ⋯
│ loop_add_compare_divide_multiply_subtract_fusion │ Unknown │ Devic ⋯
│ loop_add_broadcast_compare_divide_multiply_subtrac... │ Unknown │ Devic ⋯
│ loop_subtract_fusion.4 │ Unknown │ Devic ⋯
│ loop_add_select_subtract_fusion │ Unknown │ Devic ⋯
│ loop_add_subtract_fusion │ Unknown │ Devic ⋯
│ input_concatenate_fusion.103 │ Unknown │ Devic ⋯
│ loop_select_subtract_fusion │ Unknown │ Devic ⋯
│ loop_select_subtract_fusion.1 │ Unknown │ Devic ⋯
│ loop_add_fusion.31 │ Unknown │ Devic ⋯
│ loop_add_fusion.32 │ Unknown │ Devic ⋯
│ input_concatenate_fusion.95 │ Unknown │ Devic ⋯
│ ⋮ │ ⋮ │ ⋱
└───────────────────────────────────────────────────────┴─────────┴─────────────
[36m 8 columns and 477 rows omitted[0m
╔================================================================================╗
║ SUMMARY ║
╚================================================================================╝
AggregateProfilingResult(
runtime = 2.53900669s,
GPU_0_bfc = MemoryProfileSummary(
peak_bytes_usage_lifetime = 3.286 GiB, [90m # peak memory usage over the entire program (lifetime of memory allocator)[39m
peak_stats = MemoryAggregationStats(
stack_reserved_bytes = 0 bytes, [90m # memory usage by stack reservation[39m
heap_allocated_bytes = 3.286 GiB, [90m # memory usage by heap allocation[39m
free_memory_bytes = 7.649 GiB, [90m # free memory available for allocation or reservation[39m
fragmentation = 0.000482306, [90m # fragmentation of memory within [0, 1][39m
peak_bytes_in_use = 3.286 GiB[90m # The peak memory usage over the entire program[39m
)
peak_stats_time = 0.03221701s,
memory_capacity = 10.935 GiB[90m # memory capacity of the allocator[39m
)
metrics = Metrics(
flops = 0.034917079303061316, [90m # [flops / (peak flops * program time)], capped at 1.0[39m
bandwidth_utils = [0.41065905131950564, 0.0, 0.0],
uncapped_flops = 0.034917079303061316,
raw_time = 2.53900669s, [90m # Raw time in seconds[39m
raw_flops = 5.773761320293e12, [90m # Total FLOPs performed[39m
bf16_flops = 5.773761320293e12, [90m # Total FLOPs Normalized to the bf16 (default) devices peak bandwidth[39m
raw_bytes_accessed = [3.33719875784e11, 0.0, 0.0],
occurrences = 0,
raw_flops_rate = 2.2740236735228926e12, [90m # Raw FLOPs rate in FLOPs/seconds[39m
bf16_flops_rate = 2.2740236735228926e12, [90m # BF16 FLOPs rate in FLOPs/seconds[39m
)
)
run_toc = 88.28422379493713
[36m[1m[ [22m[39m[36m[1mInfo: [22m[39mRun toc gives you the combined time of the warmup run and the counted run from @profile, so it should be somewhat over 2x the time of profile
Visualization
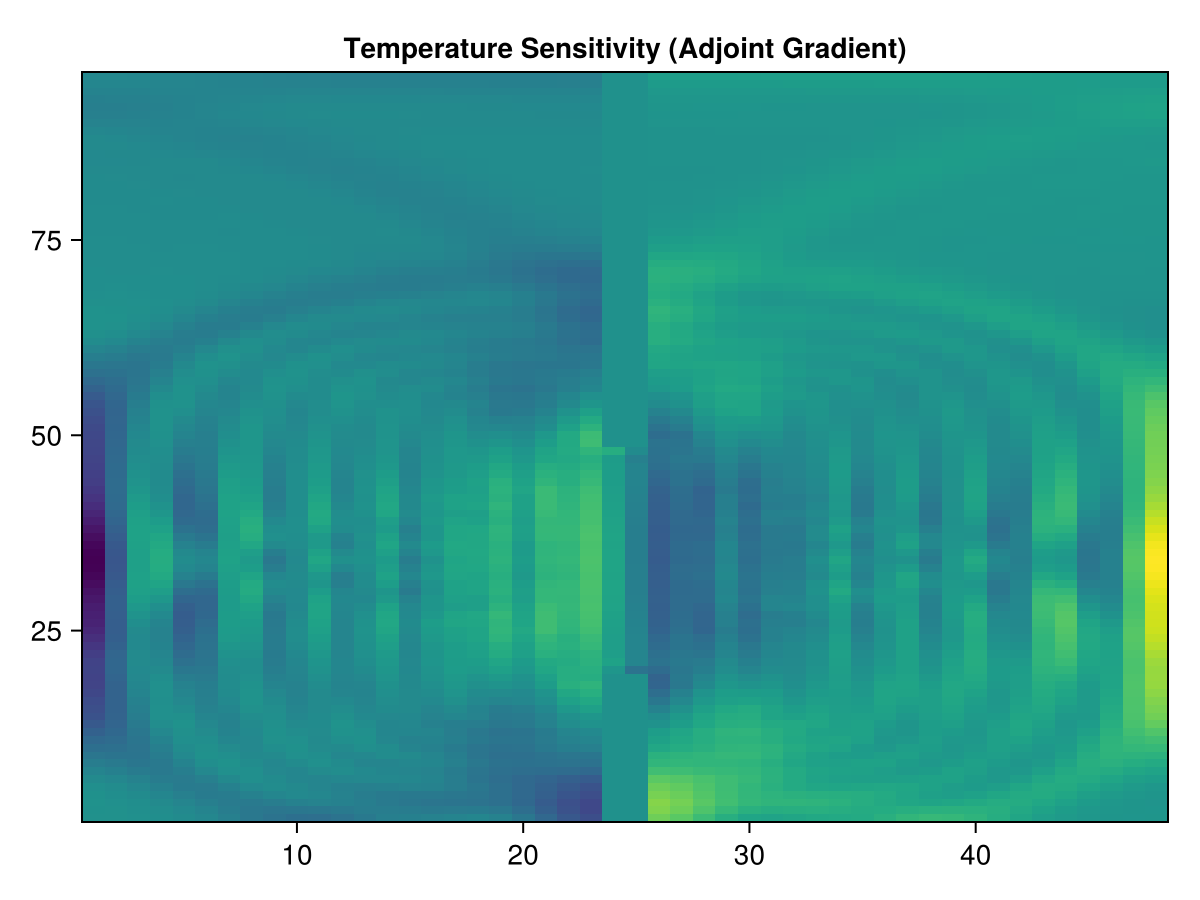
The power of the Adjoint method is visualized here. We first look at a 2D heatmap of the Sensitivity Gradient ($dT$). This plot shows exactly where the objective function is most sensitive to changes in the initial temperature field.
using CairoMakie
heatmap(Array(interior(dTᵢ, :, :, 1)),
        axis = (title = "Temperature Sensitivity (Adjoint Gradient)",))
3D Volumetric Structure
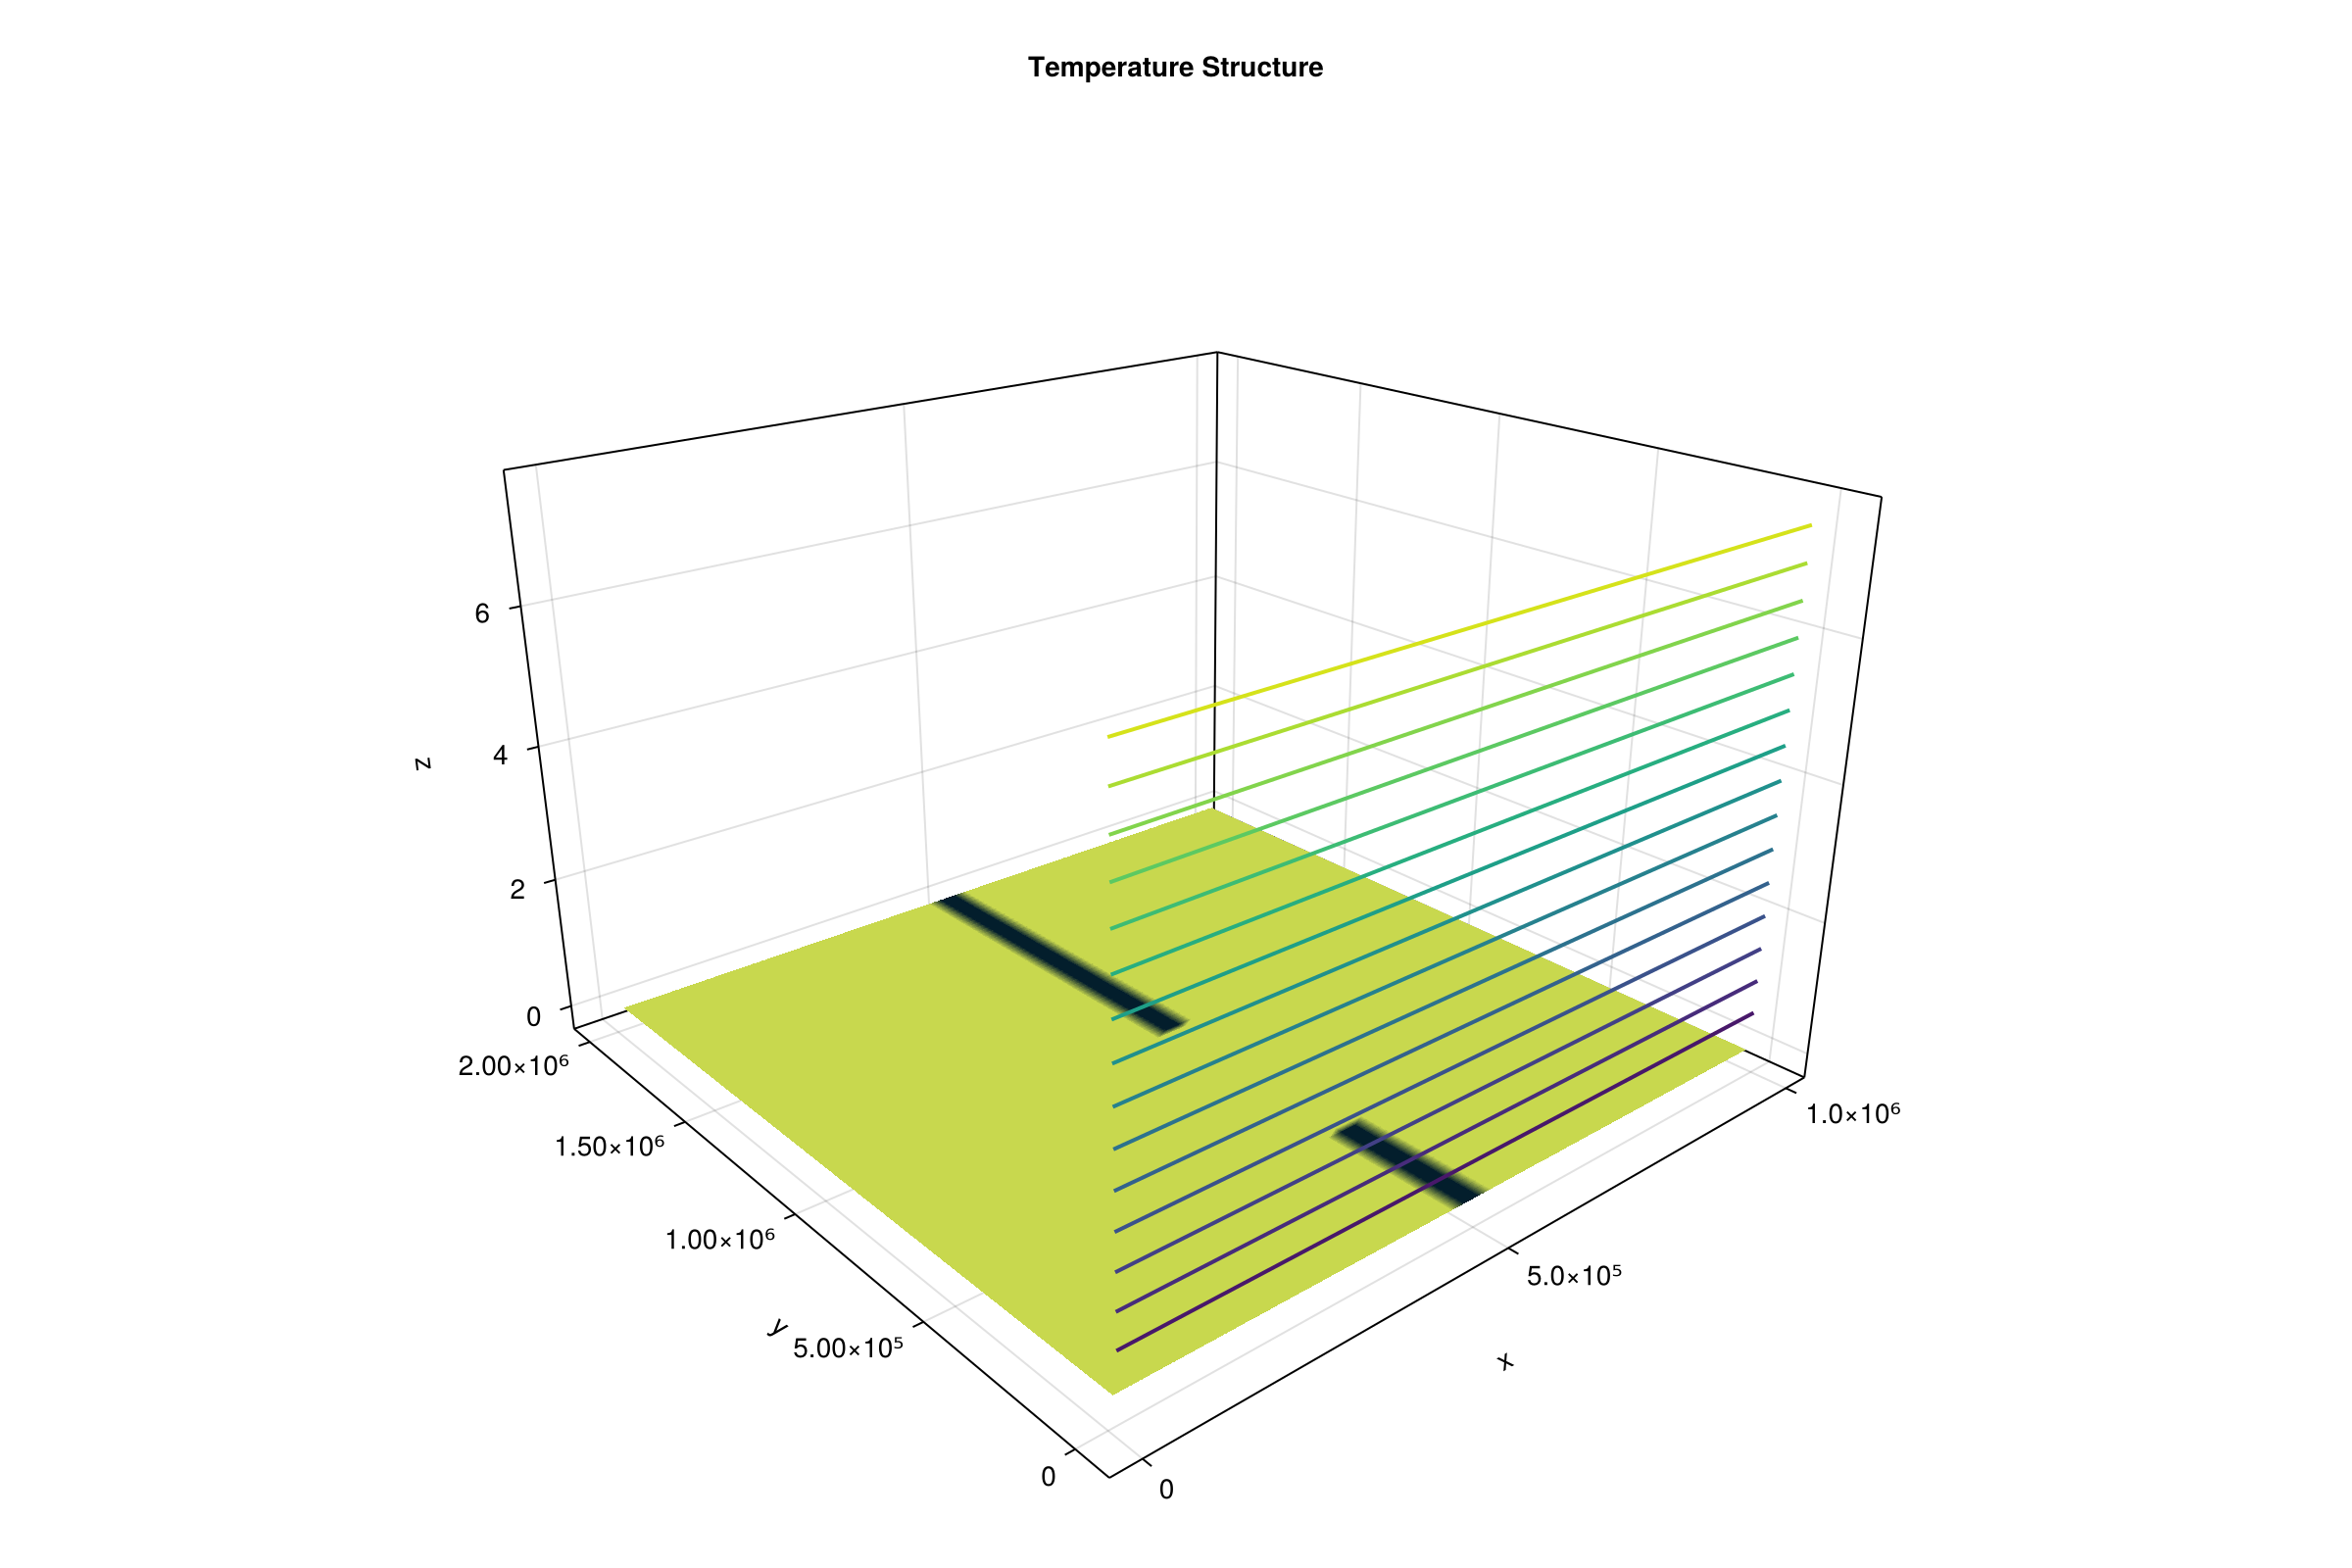
To understand the vertical impact of the topography, we plot the temperature surface alongside a cross-sectional slice of the channel.
using CairoMakie

# 1. Prepare data
T_cpu = Array(interior(model.tracers.T, :, :, :))
x, y, z = nodes(model.tracers.T)

# 2. Create Figure
fig = Figure(size = (1200, 800))
ax = Axis3(fig[1, 1], title = "Temperature Structure", perspectiveness = 0.5)

# 3. Plot a surface and a slice
# Surface (top layer)
surface!(ax, x, y, fill(0, length(x), length(y)), color = T_cpu[:, :, end], colormap = :thermal)

# Y-Slice (middle of the channel)
mid_y = Int(floor(length(y)/2))
contour3d!(ax, x, z, T_cpu[:, mid_y, :], levels = 15, linewidth = 2)

fig
Side-by-Side: Physics vs. Sensitivity
In this view, we compare the physical temperature field with the Adjoint sensitivity gradient ($dT/dJ$). This allows us to see if the model is most sensitive to features like thermal fronts or eddies.
# 1. Get the dimensions of your grid
Nx, Ny, Nz = size(model.grid)

# 2. Pull the TOP layer (index Nz) to the CPU
T_slice = interior(model.tracers.T, :, :, Nz)
T_data  = Array(T_slice)

# 3. Pull the Gradient TOP layer
dT_slice = interior(dTᵢ, :, :, Nz)
dT_data  = Array(dT_slice)

fig = Figure(resolution = (1000, 500))

ax1 = Axis(fig[1, 1], title = "Temperature (Physical State)")
hm1 = heatmap!(ax1, T_data, colormap = :thermal)
Colorbar(fig[2, 1], hm1, vertical = false, label = "Celsius")

ax2 = Axis(fig[1, 2], title = "Sensitivity (Adjoint Gradient)")
hm2 = heatmap!(ax2, dT_data, colormap = :balance)
Colorbar(fig[2, 2], hm2, vertical = false, label = "dT/dJ")

fig
[33m[1m┌ [22m[39m[33m[1mWarning: [22m[39mFound `resolution` in the theme when creating a `Scene`. The `resolution` keyword for `Scene`s and `Figure`s has been deprecated. Use `Figure(; size = ...` or `Scene(; size = ...)` instead, which better reflects that this is a unitless size and not a pixel resolution. The key could also come from `set_theme!` calls or related theming functions.
[33m[1m└ [22m[39m[90m@ Makie ~/.julia/packages/Makie/UjJJY/src/scenes.jl:238[39m
Mixed Layer Depth (MLD) Topography
The Mixed Layer Depth represents the portion of the upper ocean that is actively "ventilated" by the atmosphere. Plotting this helps us understand the vertical extent of surface forcing.
mld_cpu = Array(interior(mld, :, :, 1))

fig = Figure()
ax = Axis(fig[1, 1], title = "Mixed Layer Depth (m)", xlabel = "x", ylabel = "y")
hm = heatmap!(ax, mld_cpu, colormap = :deep)
contour!(ax, mld_cpu, color = :white, levels = 5, alpha = 0.5) # Add contour lines for depth
Colorbar(fig[1, 2], hm)
fig
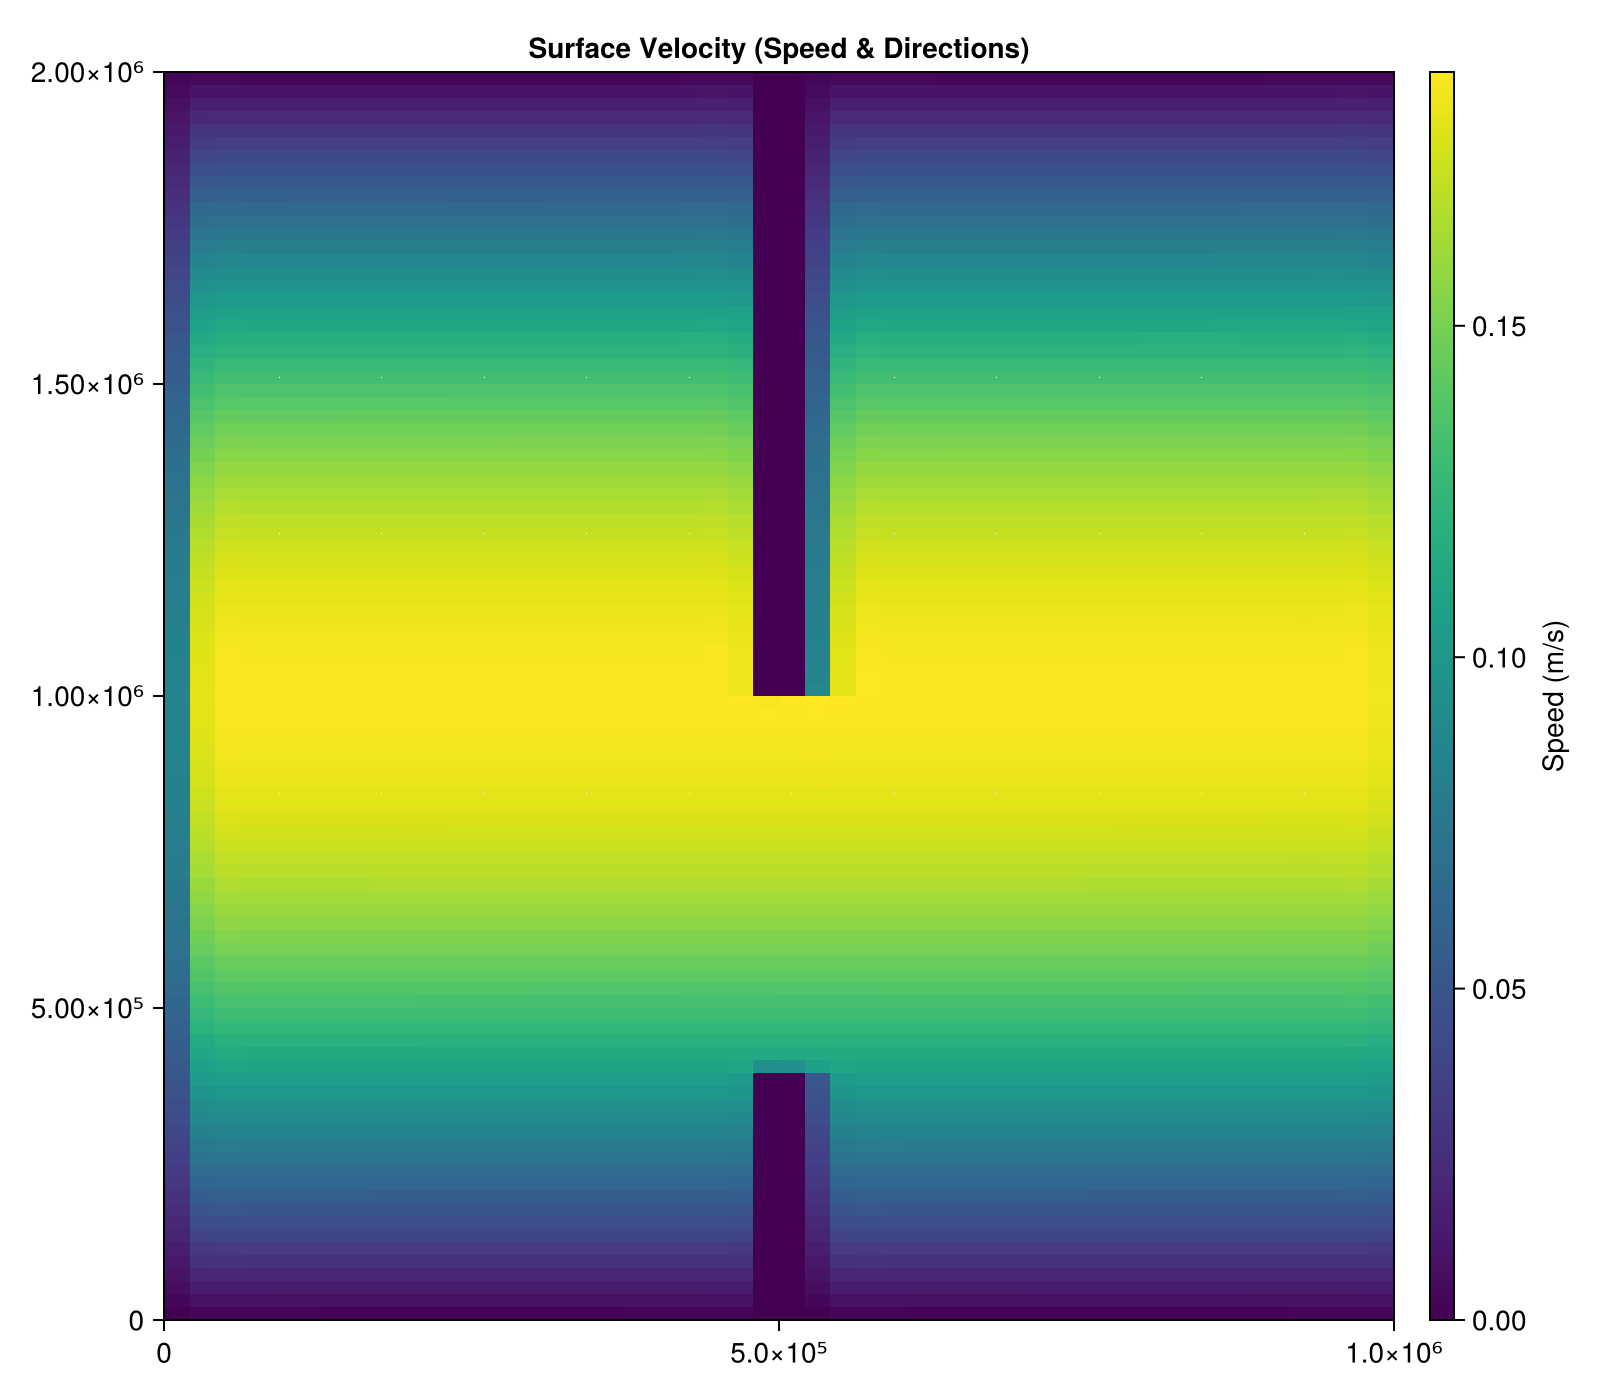
Surface Velocity
Finally, we visualize the surface currents. We calculate the speed magnitude and overlay velocity arrows. To keep the plot clean, we "subsample" the arrows, showing every 4th vector.
# 1. Get the indices and coordinates
Nx, Ny, Nz = size(model.grid)
xc, yc, zc = nodes(model.grid, Center(), Center(), Center())

# 2. Pull data to CPU
u_raw = Array(interior(model.velocities.u, :, :, Nz))
v_raw = Array(interior(model.velocities.v, :, :, Nz))

# 3. Align to common Nx, Ny grid
u_plot = u_raw[1:Nx, 1:Ny]
v_plot = v_raw[1:Nx, 1:Ny]
speed  = sqrt.(u_plot.^2 .+ v_plot.^2)

# 4. Plotting
fig = Figure(size = (800, 700))
ax = Axis(fig[1, 1], title = "Surface Velocity (Speed & Directions)")

# Background Heatmap
hm = heatmap!(ax, xc, yc, speed, colormap = :viridis)
Colorbar(fig[1, 2], hm, label = "Speed (m/s)")

# 5. Add Velocity Arrows
# We 'subsample' every 2nd or 4th arrow so the plot isn't too crowded
sub = 4
arrows!(ax, xc[1:sub:end], yc[1:sub:end],
        u_plot[1:sub:end, 1:sub:end], v_plot[1:sub:end, 1:sub:end],
        lengthscale = 0.5, arrowsize = 10, color = :white)

fig
[33m[1m┌ [22m[39m[33m[1mWarning: [22m[39m`arrows` are deprecated in favor of `arrows2d` and `arrows3d`.
[33m[1m└ [22m[39m[90m@ Makie ~/.julia/packages/Makie/UjJJY/src/basic_recipes/arrows.jl:164[39m
[33m[1m┌ [22m[39m[33m[1mWarning: [22m[39marrowsize has been deprecated in favor of tipwidth and tiplength.
[33m[1m└ [22m[39m[90m@ Makie ~/.julia/packages/Makie/UjJJY/src/basic_recipes/arrows.jl:204[39m
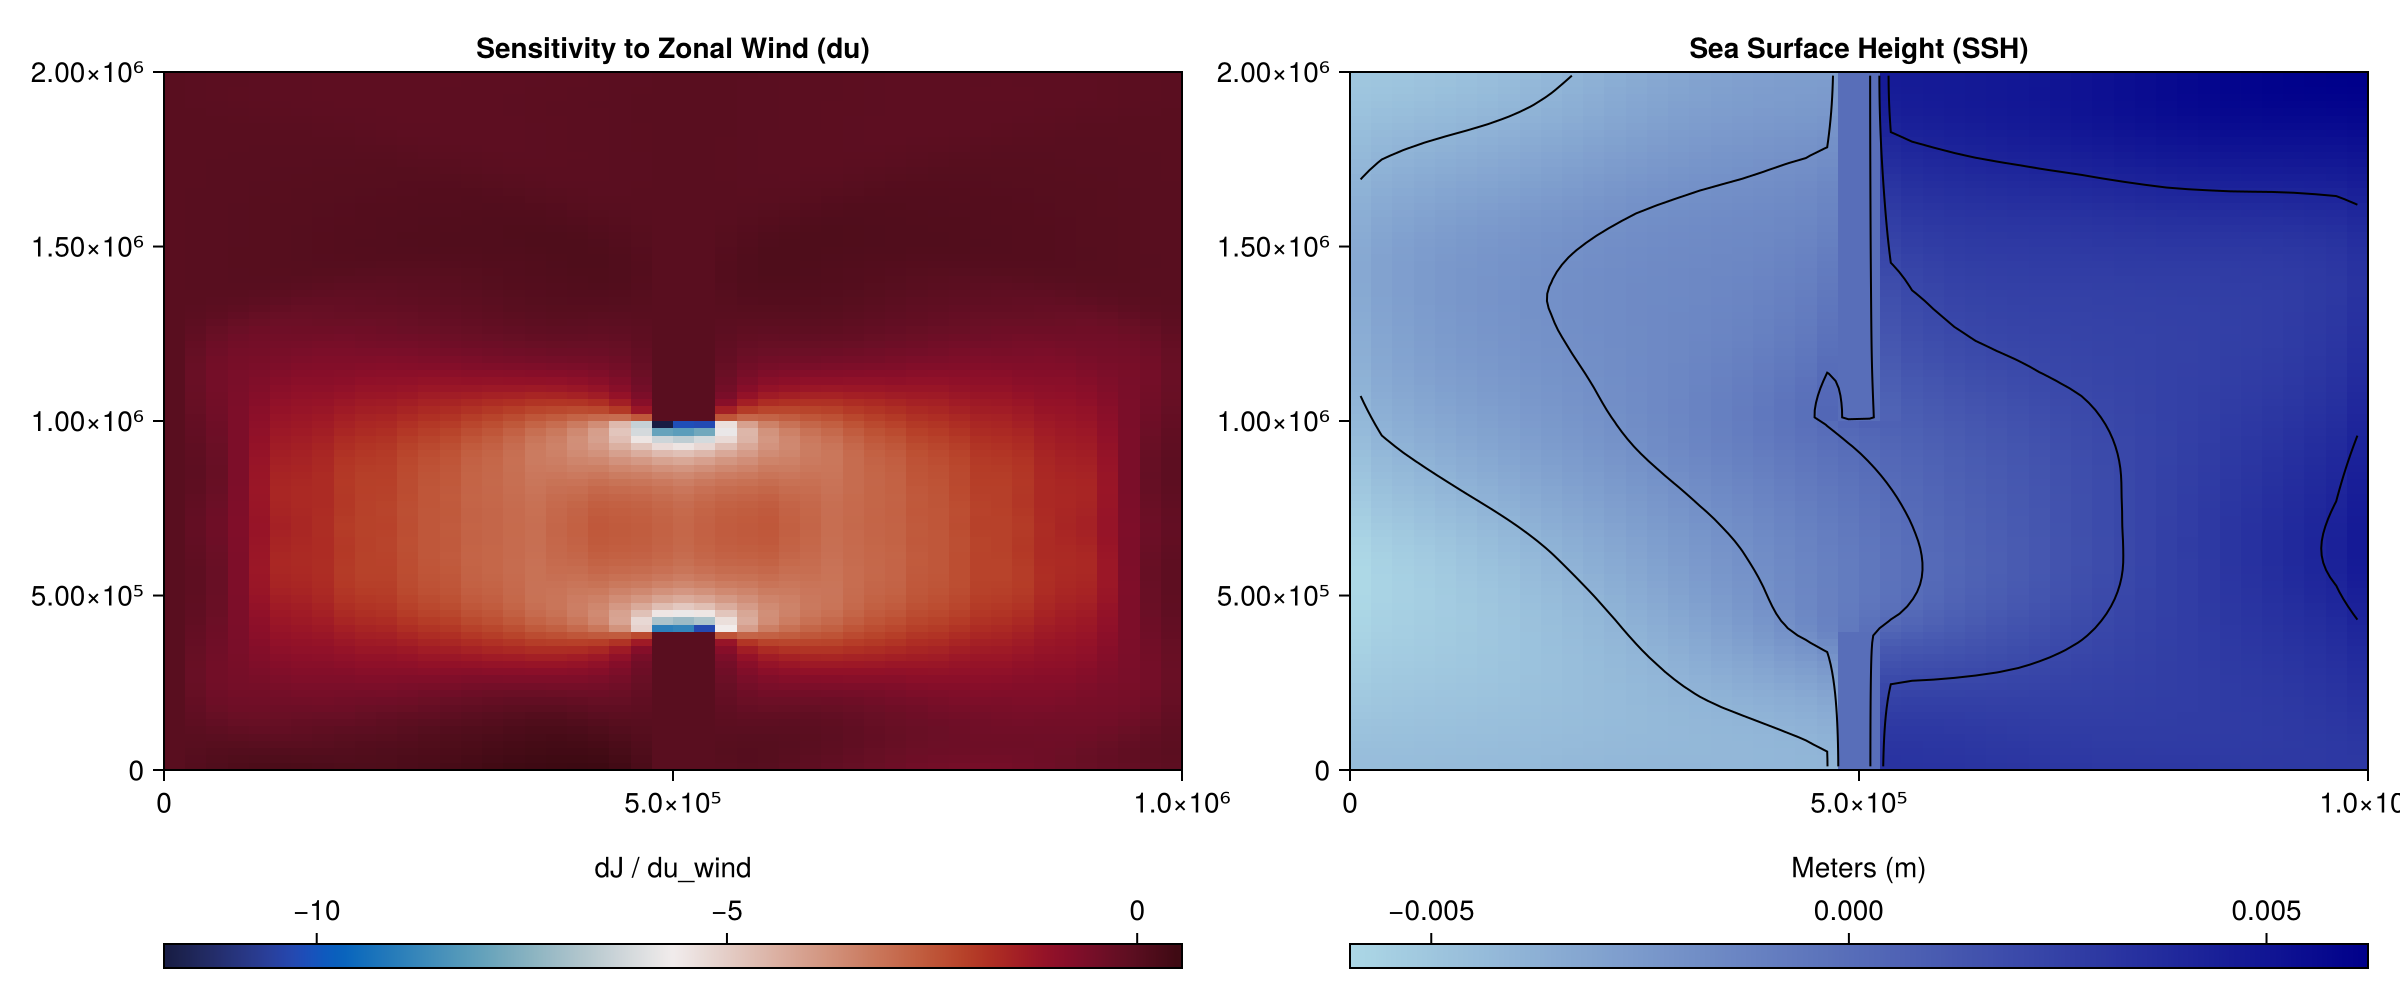
Wind Sensitivity vs. Sea Surface Height (SSH)
This final visualization compares the Adjoint Sensitivity of the zonal wind stress with the Physical State of the Sea Surface Height (SSH).
- SSH (Right): Shows the geostrophic balance of the ocean surface that drive the major currents.
- Wind Sensitivity (Left): Shows exactly where changing the wind stress would have the largest impact on our zonal transport objective. Notice if high-sensitivity areas align with strong SSH gradients (the jets).
# 1. Pull data to CPU
du_wind = Array(interior(du_wind_stress, :, :, 1))
dv_wind = Array(interior(dv_wind_stress, :, :, 1))
ssh_data = Array(interior(model.free_surface.η, :, :, 1))

# 2. Setup Figure
fig = Figure(size = (1200, 500))

# Left Plot: Zonal Wind Sensitivity
ax1 = Axis(fig[1, 1], title = "Sensitivity to Zonal Wind (du)")
hm1 = heatmap!(ax1, xc, yc, du_wind, colormap = :balance)
Colorbar(fig[2, 1], hm1, vertical = false, label = "dJ / du_wind")

# Right Plot: Sea Surface Height (Physical State)
ax2 = Axis(fig[1, 2], title = "Sea Surface Height (SSH)")
hm2 = heatmap!(ax2, xc, yc, ssh_data, colormap = :blues)
# Add some contour lines to SSH to show the 'hills and valleys' of the ocean
contour!(ax2, xc, yc, ssh_data, color = :black, alpha = 0.4)
Colorbar(fig[2, 2], hm2, vertical = false, label = "Meters (m)")

fig
Conclusion - The Power of Differentiable Oceanography
In this tutorial, we have moved beyond simple simulation into Inverse Modeling. By leveraging Reactant.jl and Enzyme.jl, we have:
-
Simulated a complex, eddying ocean channel with immersed boundaries.
-
Differentiated the entire physics engine to calculate exact gradients in a single backward pass.
-
Visualized how specific inputs (like wind and initial temperature) directly dictate the global zonal transport.
This workflow is the foundation for next-generation oceanography, enabling efficient parameter estimation, state estimation, and the quantification of uncertainty in climate projections.
If you are interested to play with the simulation, here are some possible steps:
-
Try changing the
Ntimestepsto see how sensitivities evolve over longer integration times. -
Modify the
ridge_functionto see how different seafloor geometries change the sensitivity "hotspots."
Further Reading & Citations
If you want to dive deeper into the architecture of this differentiable simulation and the technology behind Reactant.jl and Enzyme.jl, we invite you to check out our recent work:
DJ4Earth: Differentiable, and Performance-portable Earth System Modeling via Program Transformations. > Moses, W.S., Cheng, G., Churavy, V., Gelbrecht, M., Klöwer, M., Kump, J., Morlighem, M., Williamson, S., Apte, D., Berg, P. and Giordano, M., 2025. > Authorea Preprints.
This paper details how we use these tools to enable differentiable, high-performance Earth System Modeling that is portable across CPUs, GPUs, and TPUs.